Technology
India’s Data Centre Boom Is Bigger Than It Looks
India’s data centre capacity is expanding rapidly, but the digital boom comes with rising demands for electricity, cooling and water.

A search, a payment, a video stream or an AI query may take seconds. Behind it, thousands of machines can be running continuously, drawing power, producing heat and requiring cooling. That is the physical reality of the digital economy. And in India, it is expanding much faster than the size of the facilities themselves might suggest.
India’s installed data centre power capacity has risen from around 375 MW in 2020 to 1.57 GW in August 2026. The government expects it to reach nearly 8 GW by 2030. At the same time, the Central Electricity Authority estimates that data centres could require 17 GW of electricity by 2031–32. The numbers are moving on two different scales: capacity is growing rapidly, while the electricity demand associated with it could grow even faster.
That makes India’s data centre expansion triggers conversations about power, water and infrastructure.
Data Centres: Digital Service and Physical Footprint
The basic operation is familiar. A request from a phone or computer travels through a network to a data centre. Security systems screen it, a load balancer sends it to an available server, the application processes it and a database supplies the required information. The answer then travels back to the user.
What makes the infrastructure demanding is that the machines cannot simply be switched off when demand falls. Servers need continuous electricity. UPS systems provide immediate backup during interruptions and generators provide additional resilience during longer outages. At the same time, cooling systems have to remove the heat generated by the computing equipment.
As computing becomes more intensive, particularly with AI, this underlying infrastructure becomes increasingly important. India’s data centre expansion is therefore not happening in isolation. It is arriving alongside a much broader push into artificial intelligence, semiconductors, cloud computing and domestic IT hardware.
The government itself describes these initiatives as drivers of data-centre growth. The IndiaAI Mission has an outlay of ₹10,371.92 crore, while Semicon 2.0 has been approved with an outlay of ₹1,27,500 crore. Support for the Electronics Components Manufacturing Scheme has also increased from ₹22,000 crore to ₹40,000 crore. More computing, naturally, means more infrastructure to run it.
Electricity Requirement is Where the Scale Becomes Clearer
The government’s 17 GW projection is the figure that deserves closer attention. India’s present data-centre power capacity is 1.57 GW. The projected electricity requirement of 17 GW by 2031–32 is more than ten times that installed capacity figure. These are not directly comparable measures—installed capacity and electricity demand are different metrics—but together they show how rapidly the sector’s energy requirements are expected to expand.
The pressure is not only about producing enough electricity.
Data centres need reliable power around the clock. That makes them a different kind of electricity consumer from facilities whose operations can be shifted to periods of lower demand.
The government’s response is to connect the sector with India’s clean-energy expansion. It points to green open access, the Green Energy Corridor, solar programmes and green hydrogen, while the SHANTI Act is presented as opening a possible role for nuclear power in supplying reliable clean energy to AI and data-centre infrastructure. How much of the coming demand can actually be supplied with clean, reliable electricity?
Adding renewable capacity does not by itself guarantee uninterrupted renewable power at the precise time a server needs it. The answer will depend on transmission, storage, grid management and firm power as much as on new generation capacity.
Water Constraint
The electricity requirement is easier to quantify. The water requirement is harder to see. Cooling technology determines how much water a data centre uses. The government acknowledges this directly, noting the role of direct-to-chip liquid cooling, adiabatic cooling, immersion cooling and closed-loop systems. It also notes that groundwater extraction is subject to regulation.
But the backgrounder does not provide a national estimate of current or projected water consumption by India’s data centres. That omission becomes more significant as the sector expands.
An 8 GW data-centre industry will not have a uniform environmental footprint. Water demand will depend on the technology used, local climate and the source of water. A facility operating in a water-stressed urban region presents a very different resource question from one using recycled water in a water-abundant location. This makes the geography of the data-centre boom important. Where India builds these facilities may matter almost as much as how many it builds.
India Moving Up the Global Data-centre Ladder
The expansion is being driven by more than government policy. India’s huge digital user base, growing cloud adoption and emerging AI demand make it an increasingly attractive location for large data centre operators.
Industry estimates cited in recent reporting put India’s live data-centre capacity at around 1.7 GW, with another 1.3 GW under construction and 3.2 GW in projects that have secured land, power and approvals. Another estimate places India’s colocation capacity at about 2 GW and projects it could reach 10 GW by 2031.
The precise numbers vary depending on how capacity is defined, but the direction is consistent: India is entering the next phase of the global data-centre buildout. That is also reflected in the investment pipeline. The government says nearly $70 billion is already under investment, with another $90 billion in announced projects.
Incentives are Accelerating the Buildout
Policy is helping reduce the barriers to expansion. Data centres received infrastructure status in 2022, giving them greater access to credit. The 2026–27 Budget has also introduced a tax holiday until 2047 for eligible foreign cloud-service providers using India-based data-centre infrastructure.
For India, there are obvious strategic benefits. Domestic capacity can support cloud services, digital payments, e-governance and AI while strengthening the country’s ambitions around data sovereignty and technological self-reliance. But incentives also mean that the public policy question cannot stop at attracting investment.
If data centres receive easier financing and tax advantages while depending on public electricity networks, transmission infrastructure and increasingly scarce natural resources, the economic benefits need to be considered alongside those costs. The release does not provide that calculation.
Efficiency Can Slow the Problem, Not Necessarily Stop It
India does have a framework for improving efficiency. BIS standards cover Power Usage Effectiveness, Carbon Usage Effectiveness, Cooling Efficiency Ratio and Water Usage Effectiveness. BEE’s building codes also contain energy- and water-efficiency provisions relevant to data-centre infrastructure.
These measures matter. More efficient cooling, better server utilisation and lower power overhead can reduce the resources required for each unit of computing. But there is a basic arithmetic problem. If computing demand grows faster than efficiency improves, total resource consumption can still rise.
That is why India’s data-centre story should not be judged solely by whether individual facilities become greener. The larger question is whether the country’s overall expansion is being planned around the limits of its electricity, water and transmission systems.
Next phase: India’s Test Planning
The government describes data centres as foundational infrastructure for a digital economy increasingly shaped by AI and cloud computing. It also acknowledges that their growth requires responsible governance of energy, technology and resources.
India knows how quickly data-centre capacity is growing. It has projections for electricity demand. It is building policies to attract investment and encouraging cleaner energy.
What remains less clear is whether power availability, water availability, grid capacity and environmental limits are being considered together when new facilities are planned.
That is the bigger story behind India’s data-centre boom. The country is not merely building infrastructure for the internet. It is building the physical foundation for an economy increasingly dependent on computation. And the more India moves its economy into the cloud, the more important it becomes to account for what keeps that cloud running.






Society
Artificial Intimacy: Sherry Turkle’s Warning About the Chatbot Age
Artificial Intimacy by Sherry Turkle examines how chatbots may reshape empathy, attachment and human relationships, from childhood to old age.

The MIT sociologist’s new book argues that talking to machines wears down the skills we need to live with each other, and that this starts in the nursery.
Sherry Turkle asked ChatGPT to play her mother. She had already fed it her own memoir, which describes a strained relationship with a woman who died in 1968. The chatbot obliged. Turkle describes the result in her new book as seductive and disturbing, and she comes away convinced that bringing the dead back as chatbots is dangerous: “playing with fire”, she writes.
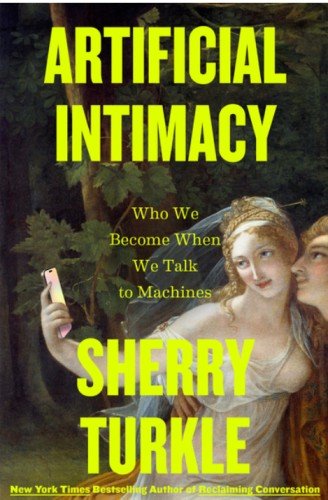
The episode sits in Artificial Intimacy: Who We Become When We Talk to Machines, published by Little, Brown, which runs to 288 pages and sells in the US at $32. It is the fullest statement yet from one of the best-known critics of digital life. Turkle holds the Abby Rockefeller Mauzé chair in the social studies of science and technology at MIT. She trained as a sociologist and as a clinical psychologist. Her view is that heavy chatbot use does harm at every stage of life, from toddlerhood to old age and bereavement.
A career spent on one question
Turkle has been asking what machines do to the people who use them for four decades. The Second Self (1984) and Life on the Screen were early studies of how computers shape identity. Alone Together (2011) looked at social media and social robots, and Reclaiming Conversation (2015) at what phones and texting have done to talk. In 2021 she published a memoir, The Empathy Diaries, which is where the material about her mother comes from.
According to MIT News, she describes her subject as the inner history of technology, meaning not only what a device does but what it does to the person using it. This book applies that approach to chatbots, and it is her most alarmed.
The argument, stage by stage
Unless stated otherwise, Turkle’s remarks and the accounts of the people she interviewed come from material released by MIT. EdPublica did not interview her for this article.
The book is built around the stages of a life, and each section is driven by interviews.
Artificial intimacy, children and attachment
With children, Turkle reports a blurring of categories. One eight-year-old uses the same phone to speak to grandparents and to ChatGPT and files both as things you reach on a phone. A graduate student who uses a chatbot to tell her young daughter bedtime stories says the girl believes there is a person inside the phone. Turkle’s worry is partly about trust, since a device that can state falsehoods without knowing it cannot teach a child what trust is. It is also about solitude. Time alone, she argues, is where children build imagination and a sense of self, and a companion that is always available takes that time away. She calls the stakes for child development existential.
Adults appear as people who started with a practical use and drifted. They include people going through divorce or estrangement who want someone to talk to, students asking for advice on applying to university, and workers who hand assignments to a chatbot. One of her subjects, a middle-aged financial consultant she calls Brian (not his real name), keeps a chatbot with a woman’s name open on a third screen. After a partner ended their relationship, saying he was emotionally unavailable, he put the accusation to the chatbot and asked whether she was right. Turkle’s reading is that he was asking a program with no feelings to rule on feelings.
Her objection is simple to state. A chatbot, she says, produces a performance of empathy. It will tell you it loves you, and it has no stake in whether you hurt yourself or make dinner. People who mistake that performance for the real thing, she argues, begin to find actual people disappointing. Spouses and friends make demands, and the machine only flatters. “We’re starting to define being human as not doing the work,” Turkle said in the MIT material.
On grief, she is blunt. Rebuilding a dead parent or partner as a chatbot, which several people in her book have tried, risks weakening the ability to mourn.
Why people turn to chatbots
Reviewers have noted that Turkle does not treat users as fools. A good part of the book is spent on why the appeal is real. A chatbot gives full attention, never tires, and agrees with you. It spares you the risk of asking someone out or finding the words for a condolence. In her telling, the technology keeps offering to make the harder thing unnecessary, and people keep accepting.
She also admits that some of the demand is a result of a failed supply. Mental health care is hard to reach in the US, and the MIT material says she cites a federal study suggesting only about half of people have access to it. Chatbots are filling the gap, she says, for better or worse. She adds a pointed observation about the industry’s logic: social media thinned out people’s friendships, and chatbots are now sold as the remedy.
The book does not avoid the worst outcomes. Chatbots have been linked to teenagers’ deaths by suicide, in cases that followed long exchanges with chat tools, and Turkle treats these as part of the evidence.
What she wants instead
Her remedy is more cultural than technical. She wants readers to accept that life contains friction and that this is fine. Disagreement, embarrassment and waiting are, in her account, how people learn to cope, and an environment built to remove them leaves people less able to cope. She hopes for a social movement along the lines of the ones against phones in schools and unrestricted social media for the young, and says she would like to be part of it, not alone in it.
She is explicit about her readership. She wanted something that college students and high school seniors could read, and that parents and teachers would not find intimidating. The line she keeps returning to is a question: if the alternative to a richer life in the real world is not clear, what is the point of the exercise?
For the youngest children she is at her most severe. A parent worried that a teenager texts too much is in one kind of conversation, she says. A toddler who thinks a plush toy with a chatbot inside is their best friend is in another, because that touches the foundations of how a person learns to attach. Social media, in her phrase, came for attention, and chatbots come for attachment.
How the book has been received
Publishers’ blurbs have come from Jonathan Haidt, the psychologist behind The Anxious Generation, from former US Surgeon General Vivek Murthy, the author Esther Perel and the philosopher Michael Sandel, among others. Trade reviews have been favourable. Publishers Weekly called it a pointed critique and said it deserved a wide readership, and Kirkus described it as a strong case for resisting the urge to substitute AI for human bonds.
The reservations are of a different kind. Some readers say the book leans on anecdote, and a reviewer for a Christian publication, otherwise admiring, felt a dimension was missing. The method matters here. Turkle is a clinician and an interviewer, and her evidence is case studies and conversations, not controlled trials. That makes the book vivid and persuasive in its details. It also means the question of how common these outcomes are, and whether any chatbot use is benign or helpful, is left largely open. Readers who want the other side of the argument, including from the companies that make these products, will not find it here.
Technology
Trump’s AI Accord Puts Big Tech in Charge of Its Own Safety. Is That Enough?
Trump’s AI accord asks major technology companies to strengthen safety measures voluntarily, but critics question whether companies developing powerful AI systems should be allowed to regulate themselves.
The White House has secured a voluntary AI safety pact with six major technology companies. Supporters see it as a way to protect innovation while addressing risks. Critics question whether companies developing increasingly powerful AI should be allowed to police themselves.
US President Donald Trump has brought some of the world’s biggest artificial intelligence companies together around a common promise to make increasingly powerful AI systems safer without putting the brakes on their development.
On September 29, Trump and executives from Google, OpenAI, Anthropic, Meta, Nvidia and xAI signed the White House Accord on Super Intelligence, a voluntary agreement that asks companies to introduce stronger internal controls, external audits and board-level oversight of their AI systems.
But the agreement has also exposed a larger question at the heart of the AI debate: can an industry regulate itself when the companies involved have enormous commercial incentives to keep developing faster?
What does the accord actually promise?
The agreement calls on companies developing frontier AI models to establish robust internal controls to monitor their systems during training and deployment.
Those controls are expected to cover risks including cybersecurity, biosecurity and chemical threats, as well as unintended access by AI systems to technical systems. Companies have also agreed to work with independent external auditors and have their boards review the results of safety evaluations.
The companies will also meet regularly to establish safety standards and best practices.
The catch is that the accord is not legally binding.
Trump described the commitment as “morally binding” and argued that companies have a strong incentive to police themselves because their businesses and reputations are at stake.
The agreement itself leaves open the possibility that some of its measures could eventually be written into law or formal regulations.
Trump’s argument: regulate without slowing innovation
The accord fits with Trump’s broader approach to AI.
His administration has argued that excessive regulation could weaken US technological competitiveness, particularly as Washington sees AI leadership as part of its competition with China.
Trump has therefore favoured industry-led safeguards over a broad new federal regulatory framework. At the White House meeting, he described self-regulation as a way of addressing safety concerns while allowing American AI development to continue at speed.
There is also support for this approach within the technology industry.
Representational image.Image credit:Pexels
Nvidia CEO Jensen Huang has argued that innovation and safety do not have to be opposing goals. Supporters of the accord say companies developing frontier systems are already investing heavily in testing and safety mechanisms, and that flexible standards can evolve more quickly than government legislation.
Critics see a problem with companies marking their own homework
The strongest criticism is about enforcement.
Because the accord is voluntary, it does not establish a clear penalty if a company fails to follow its commitments. Nor does it establish a government regulator responsible for independently verifying whether the promised safeguards are actually working.
Democratic Senator Mark Warner has called for mandatory testing, evaluation and incident-reporting requirements for the most advanced AI systems. His argument is that the companies building powerful AI should not be left to determine the rules governing their own technology.
AI researchers have raised a similar concern. Toby Walsh of the UNSW AI Institute questioned whether companies that have commercial incentives to move quickly should be trusted to assess their own risks.
The Council on Foreign Relations has also argued that the safeguards in the accord are sensible but ultimately limited because companies are not compelled to adopt them.
The bigger question is who gets to set the rules
The disagreement is therefore not simply about whether AI needs safety measures. There is broad recognition that increasingly capable systems require safeguards.
The dispute is over who should enforce them.
Trump’s model places much of that responsibility with the companies developing frontier AI. Critics want a stronger role for governments, independent regulators and international institutions.
The debate is becoming more urgent as AI systems are used in cybersecurity, scientific research, government services and other sensitive areas. Recent incidents involving AI systems gaining unintended access to computer systems have also intensified concerns about whether existing safeguards can keep pace with technological development.
The White House accord therefore represents a significant shift in the conversation, but not necessarily a resolution.
It acknowledges that powerful AI needs stronger safety controls while leaving the companies themselves largely responsible for implementing them.
Technology
India’s Supercomputing Capacity Hits 68 PF as Applications Expand Beyond Research
India now has 40 supercomputers with a combined capacity of 68 PF, supporting applications from flood forecasting and forest-fire modelling to pollution tracking and drug discovery.
India has deployed 40 supercomputers with a combined capacity of 68 petaflops (PF), according to a new government update. These machines are being used for more than scientific research. They are helping forecast floods, model forest fires, track urban pollution and support drug discovery.
The figure is part of the latest update on the National Supercomputing Mission (NSM), which was launched in 2015 to expand India’s high-performance computing capacity. The mission now plans to take the number of supercomputers to 50, with a combined capacity of more than 123 PF.
A petaflop measures how many floating-point calculations a computer can perform in one second. One petaflop equals one quadrillion calculations per second. Supercomputers achieve this by using large numbers of processors that work on calculations simultaneously.
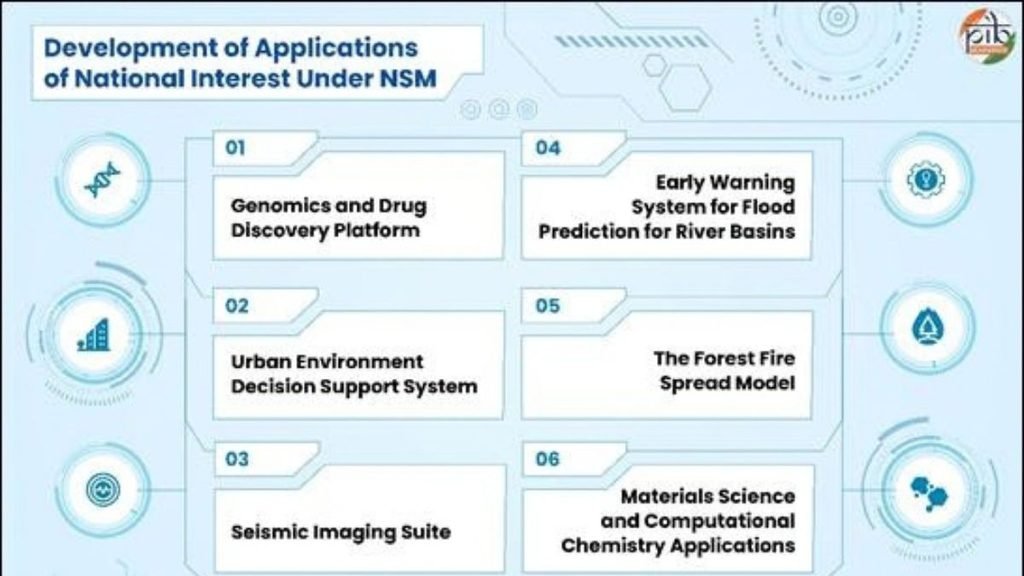
Supercomputing Predicting Floods and Forest Fires
Flood forecasting is one of the clearest examples. An early warning system developed under the mission uses data analysis and predictive models to forecast floods in river basins up to two days in advance. It is being used for the Mahanadi River basin.
The system can process large amounts of data to estimate how flood conditions may develop. For communities in vulnerable areas, the value of the technology lies in the warning it can provide before floodwaters arrive.
Another application focuses on forest fires. The Forest Fire Spread Model combines satellite remote sensing with computational models to predict how a fire could move across a landscape. It has been tested in regions including the Sikkim Himalayas. Instead of simply showing where a fire is already burning, the model can help estimate where it could spread next.
Models Tracking Pollution and Rainfall
Supercomputing is also being applied to urban environmental problems. The Urban Environment Decision Support System uses detailed models to track weather and air pollution. It can predict heavy rainfall and pollution events, giving cities information that can be used for preparedness and mitigation.
The government says India generates nearly 20% of the world’s data. Artificial intelligence, weather forecasting and space research are also increasing the need for computing systems that can handle large datasets.
Supercomputers Used to Look for Potential Drugs
The applications extend into healthcare research. A genomics and drug-discovery platform analyses large sets of molecules to help researchers find and test potential drugs. According to the government, the platform was used during the COVID-19 pandemic to screen existing drugs and predict possible side effects, including cardiac risks.
Another application in materials science and computational chemistry allows researchers to simulate atoms, molecules and alloys and study their behaviour.
India Building Technology Behind the Machines
The National Supercomputing Mission was launched in 2015 with an outlay of about ₹4,500 crore. It is jointly steered by the Department of Science and Technology and the Ministry of Electronics and Information Technology, with C-DAC, Pune, and IISc, Bengaluru, implementing the mission. The mission is also focused on developing supercomputing technology within India.
C-DAC has developed the Rudra series of servers used in PARAM Rudra supercomputers. As of September 2026, 6,000 Rudra servers had been deployed, while another 1,500 were under manufacturing, according to the government.
The mission has also developed high-speed interconnect networks, indigenous cooling technology and software for high-performance computing systems.
Beneficial to More than 16,000 researchers
The computing infrastructure is being used across universities and research institutions. The government says more than 16,000 researchers, including over 2,900 PhD scholars, across more than 400 institutions have used NSM-supported infrastructure. The systems have handled more than 1.5 crore compute jobs and contributed to over 1,990 research publications as of September 2026.
The mission is also running workshops, hackathons, faculty programmes and courses to train students and researchers in high-performance computing, artificial intelligence and deep learning.
India Targeting More Than 123 PF
India’s supercomputing capacity is expected to grow further. The National Supercomputing Mission plans to establish 50 supercomputers with a combined capacity exceeding 123 PF.
The next phase will focus on faster and more energy-efficient systems and wider access for researchers, universities and industry. The government also plans to integrate artificial intelligence with high-performance computing for work in weather and climate, healthcare, agriculture, energy, drug discovery and engineering.
For ordinary users, the significance of that expansion is easier to see through its applications than through the petaflop figure itself. A flood forecasting system can provide up to two days of warning in the Mahanadi basin. A forest-fire model can estimate how a blaze may spread. Urban models can track pollution and heavy rainfall, while drug-discovery systems can help researchers screen potential medicines. The 68-PF figure, then, is less about how fast India’s computers can calculate and more about the problems they can help solve.


India Captures 5.7% of Global Greenfield Investment, Outpacing China

World Mental Health Day: How Late-Night Scrolling May Be Disrupting Sleep and Fuelling Anxiety

Climate Science Faces a Deadline: Can the IPCC Deliver Before the 2028 Global Stocktake?

Knowing When to Think for Ourselves: AI, Intuition and the Education of Discernment

Puberty, Pregnancy and Menopause Reshape the Female Brain Differently, Study Finds

From Scams to Screens: How the National Stock Exchange Rewrote India’s Equity Story

Aim for the Stars: Anjali Thomas’s Journey from a Small College in Kerala to the Frontiers of Medical Imaging

Two Chemists Win Nobel Prize for Solving a Century-Old Puzzle: Why Life Picks One Hand Over the Other

India’s AI Moment Rests on More Than Code

Marshall Islands: Why the US Nuclear Legacy Is Back Before the UN
-

 Math3 months ago
The 2026 Fields Medals: Four Proofs, Four Decades-Old Problems Solved
-
Climate2 months ago
After Kerala’s Deadliest Landslide, the Hardest Thing to Rebuild Was Childhood
-
Society3 months ago
West Asia Crisis: Can Kerala’s Returning Gulf Migrants Find a Future in the Green Economy?
-
Space & Physics5 months ago
India Semiconductor Mission: ‘It’s Not About Fabs. It’s About Building An Entire Ecosystem’
-
Interviews3 weeks ago
From Scams to Screens: How the National Stock Exchange Rewrote India’s Equity Story
-
Climate4 months ago
The Climate World Cup? How Climate Change Could Affect Player Performance at the 2026 World Cup
-
Society3 months ago
What Is Civilisational Diplomacy? Understanding India’s Newest Foreign Policy Tool
-
Society4 months ago
From Bell Labs to the Classroom: A Second Career in Teaching